Isolated Vocal Tracks: AI Extraction and Use Cases
The most popular advice about isolated vocals is also the most misleading: upload a song, remove the music, and expect a clean a cappella ready for release. That workflow can produce useful results, but the output is usually a reconstruction of a finished mix, not the original studio vocal. The difference matters whenever you plan to remix, transcribe, classify, publish, or use the track as evidence.
Modern separation tools can recover remarkably usable vocal material from complex recordings. They can also leave behind faint drums, smeared consonants, metallic high frequencies, pumping ambience, or traces of instruments that share the vocal's frequency range. Treat isolated vocal tracks as processed audio with a specific quality ceiling, then choose the cleanup, analysis, or creative workflow that matches that ceiling.
Understanding Isolated Vocal Tracks and Their Limits
An isolated vocal track is a version of a mixed recording in which a system estimates the vocal component and suppresses the accompaniment. It isn't automatically the same as a clean a cappella. A studio a cappella comes from the original recording session, before the vocal was combined with instruments, mix bus processing, room effects, and lossy delivery formats. An extracted vocal is reconstructed after those elements have already interacted.
That distinction explains why an isolated vocal may sound convincing in one passage and unstable in the next. The system has to infer which time-frequency patterns belong to the singer and which belong to guitars, cymbals, backing vocals, reverberation, or compression artifacts. Dense arrangements remain difficult, and recent work on research on robust singing voice separation shows that quality is still variable rather than clean by default.
Salvage versus session audio
The practical mindset is simple. You're salvaging a performance from a mix, not recovering a hidden WAV file. That salvage may be excellent enough for a mashup, rehearsal track, dialogue edit, or research feature, but it may not withstand solo listening or close mastering.
Common problems include:
- Musical leakage: A bass note, snare transient, guitar resonance, or backing vocal remains under the lead.
- Spectral smearing: Sibilants and breath sounds lose their natural edge because they overlap with cymbals and other high-frequency material.
- Metallic or watery tone: Neural processing can create modulation artifacts around sustained vowels and harmonies.
- Room inconsistency: Reverb may be partly removed, partly retained, or separated into a sound that follows the vocal unevenly.
- Timing damage: Fast consonants and vocal attacks can soften when the model prioritizes the dominant accompaniment.
A vocal can still be valuable with these imperfections. The right question isn't “Is this identical to the original?” It's “Does this output preserve the information and musical detail my next step requires?” A DJ may tolerate leakage that would invalidate a forensic comparison. A producer may hide artifacts beneath a new arrangement, while a transcription system may benefit from a vocal that sounds unpleasant but retains articulation.
Practical rule: Judge the extraction in context, at the level where you'll use it. A track that fails as a solo may work well inside a dense remix, but that doesn't make it a studio stem.
Comparing AI Separation and Traditional Studio Stems
AI extraction is not a cheaper version of a studio stem. The two files come from different stages of production and serve different purposes. Official studio stems are exported from the multitrack session, while AI separation estimates a vocal from a finished stereo or multichannel mix. One preserves production decisions. The other provides access to recordings that were never released as individual parts.
Before neural models became common, engineers used the stereo image to reduce centered material. Since lead vocals were often center-panned, channel cancellation and other stereo manipulation could lower the vocal or accompaniment, though the results were limited. Earlier research also used principal component analysis, independent component analysis, and non-negative matrix factorization. Deep learning later improved separation quality and processing time, making isolated vocals a major audio research area (overview of audio source separation).
The practical difference
| Feature | Official Studio Stems | AI Source Separation |
|---|---|---|
| Source | Original multitrack session | Finished stereo or multichannel mix |
| Vocal fidelity | Usually preserves the recorded vocal and intended processing | Depends on the mix, model, and overlap between sources |
| Availability | Limited to files released or supplied by rights holders | Works from accessible recordings, subject to rights and input quality |
| Leakage | Normally absent between the supplied tracks | May include instruments, backing vocals, or ambience |
| Workflow control | Offers direct control over production elements | Offers flexible recovery after the mix is printed |
| Best use | Commercial remixing, archival work, final production | Practice tracks, edits, analysis, experimentation, and difficult recovery tasks |
| Main risk | Access, licensing, and incomplete stem sets | Artifacts, phase problems, and incorrect source assignment |
Studio stems remain the right choice for a finished commercial master or archival reconstruction. They retain the original vocal compression, send effects, double-track balance, and automation. They also let an engineer mute or reshape an element directly, instead of asking a model to infer where the vocal ends and another source begins.
AI separation earns its place when the session files are unavailable. It can turn a released mix into a workable reference, practice track, edit source, or analytical sample without rebuilding the entire production. In forensic and research workflows, the isolated result can expose phrasing, edits, backing-vocal relationships, or performance details that are difficult to inspect in the full mix. Those uses do not make the output authentic. The model sees patterns in the supplied audio and produces a plausible estimate, not the artist's original track.
If the deliverable requires a finished commercial master, seek authorized stems first. Use AI extraction when access is the constraint, or when a rough but functional result provides more value than perfect provenance.
Current research also compares audio-only systems with audiovisual methods that use mouth movement alongside the soundtrack. Visual cues can help separate overlapping singing voices, especially when several performers share similar frequency ranges, but they do not restore the original recording (audiovisual singing voice separation research).
Measuring Extraction Quality and Audio Artifacts
A vocal can sound convincing in a full mix and fail under examination. Engineers need both controlled measurements and deliberate listening to determine whether an extraction preserves useful performance detail or merely produces a plausible foreground signal. Metrics show how much target vocal remains and how much accompaniment leakage or processing residue enters the result. They help explain why one file supports transcription while another breaks down when soloed.
Signal-to-noise ratio, or SNR, compares desired vocal energy with separation error. Here, error includes backing-track leakage and artifacts created during extraction. A higher value generally means the recovered vocal dominates the residue. One stem-agnostic evaluation reported at least 7.4 dB SNR for vocals on the MoisesDB benchmark, with performance comparable to HT-Demucs in that test setup (source-separation evaluation).
What the metrics tell you
SI-SNRi, or scale-invariant signal-to-noise ratio improvement, measures how much cleaner a system makes a mixture while reducing the effect of overall level differences. It is useful when the extracted output and reference do not share the same gain. A cross-domain singing-voice system reported 22.3 dB SI-SNRi on WSJ0-2mix and 19.5 dB SI-SNRi on WSJ0-3mix (cross-domain separation benchmark).
cSDR, a distortion-aware SDR measure, evaluates the balance between recovered source energy and distortion. A 2025 high-performance vocal separation model reported 11.03 dB cSDR, which its authors described as the strongest reported result at that time. Such benchmark results depend on defined datasets and test conditions. They do not predict the score of an online tool on a particular commercial recording.
Listen for failure modes
Numbers need targeted auditioning. Solo the vocal first, then return it to the backing track. Masking in the complete mix can conceal artifacts that become obvious in isolation.
- Check the first consonant of each phrase. “T,” “K,” and “S” sounds often expose smearing or musical residue.
- Inspect sustained vowels. Warbling, chorusing, and metallic motion point to unstable source estimation.
- Listen during drum hits. A kick or snare shadow that pumps through the vocal suggests leakage or mix-bus interaction.
- Compare quiet phrases. Breaths and room tails may vanish, then reappear as unnatural fragments.
- Test mono compatibility. Phase-related processing can sound acceptable in stereo and weaken after summing.
Phase cancellation still matters when a separated vocal is combined with parts of the original mix. This guide to phase cancellation in audio explains why similar signals can reinforce each other in one context and cancel in another.
For production, single-digit SNR may remain workable when a new arrangement masks the residue. Lyric transcription and detailed performance analysis require closer validation because the same contamination can alter recognition or bias interpretation. Use the metric to set the listening standard, not to replace it.
Real-World Applications Beyond Music Production
Karaoke and remixing are easy starting points, but they miss the more analytical value of isolated vocal tracks. A separated vocal can serve as a focused object for speech analysis, style classification, dataset labeling, dialogue repair, and forensic review. Clean listening is helpful, yet the output's real value may depend on whether it preserves articulation, rhythm, timbre, and timing without introducing misleading artifacts.
An ISMIR study classified three-second vocal snippets from commercial urban music as singing or rap with over 91% accuracy (ISMIR study on isolated vocal tracks). For practical work, the label matters less than the preserved cues. Short excerpts can support downstream analysis when separation retains phrase delivery and vocal character, even if the stem is not suitable for release.
Analysis needs different standards
A producer checks whether a vocal fits a beat. A researcher checks whether a measurable feature survives processing. A forensic analyst checks whether separation has altered the material in ways that could affect interpretation. These uses require different acceptance criteria.
Separation can produce cleaner annotations for speech and singing research and reduce unrelated material presented to a classifier. It can support vocal-style tagging, segmentation, and feature extraction, particularly when the target depends on articulation or rhythmic delivery instead of a pristine tone. Keep the original mix, record the separation settings, and treat the extracted stem as processed material rather than untouched evidence.
The same discipline applies to bioacoustics. A recording may contain an individual call, a bird, an animal, or a human voice within substantial background noise. Audio-visual separation research has examined scenes where visual cues help identify a target source, with one 2025 study reporting 71.88% test accuracy under its stated evaluation conditions (audio-visual source separation study). That result describes the study's data and method, not the expected performance of every tool or recording.
Podcasters and interview editors usually prioritize intelligibility over musical isolation. A separator can reduce competing music or environmental sound, while aggressive processing may damage breaths, consonants, and room tone. A podcaster workflow for isolating and cleaning audio works best as a controlled edit: compare the processed speech with the original, keep a safety copy, and apply restoration after separation. In dense mixes, inspect difficult phrases manually because AI extraction can leave musical residue or reshape consonants.
Forensic and research workflows should preserve both versions and document every processing step. Separation is preprocessing, not proof that unwanted sound has disappeared.
Creating Custom Isolations with Natural Language AI
Fixed stem categories work well for familiar tasks such as vocals, drums, bass, and accompaniment. They become less useful when the target is a specific sound inside a video or field recording. A natural-language workflow lets you describe the source directly, such as “piano melody,” “crowd cheering,” “lead vocals,” or “dog barking,” then returns the target and the remainder as separate outputs.
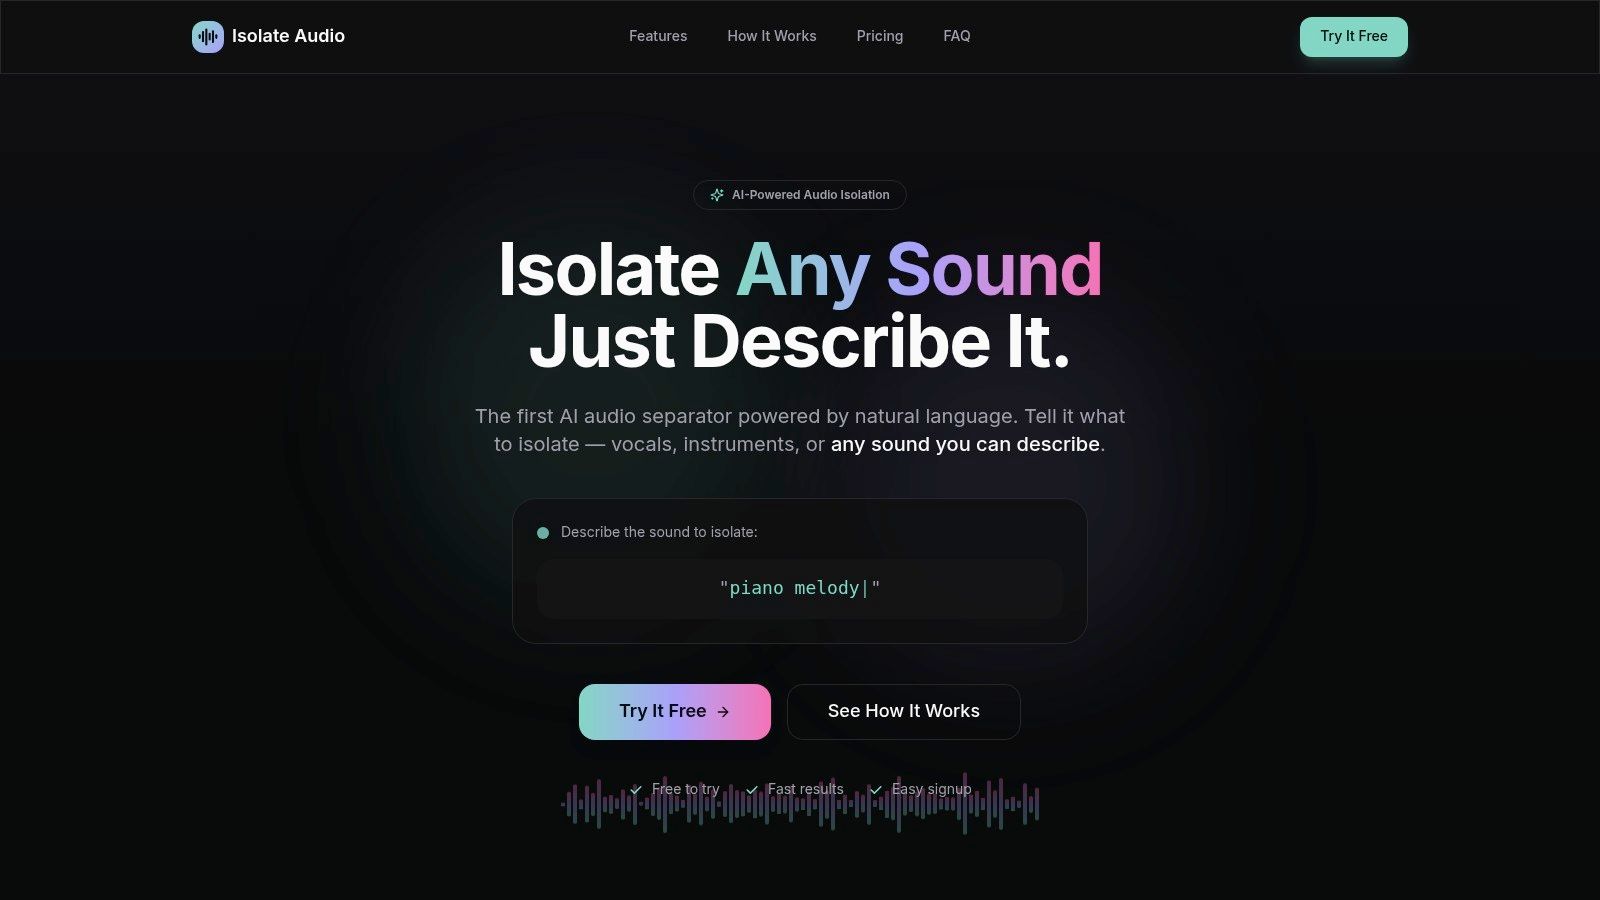
A reliable workflow starts with the cleanest available input. Upload the original file rather than a screen recording or repeatedly compressed export when possible. Isolate Audio accepts common audio and video formats, including MP3, WAV, FLAC, M4A, OGG, MP4, and WebM, then processes the request in the cloud.
Write prompts that identify the source
Use a prompt that describes what should remain, not just what should disappear. “Isolate the lead vocal” is more precise than “remove the music,” because the latter leaves the target ambiguous. Add a qualifier when the recording contains multiple related sources, for example “isolate the main female singing voice and exclude backing vocals.”
For non-musical material, name the acoustic event and its role. “Extract the piano melody while leaving the vocal and drums in the remainder” gives the system a clearer target than “get the piano.” The natural-language audio separation examples can help you refine descriptions for unusual sources.
Choose the quality setting according to the job:
- Best: Use it when the vocal will be exposed, edited, or analyzed closely.
- Balanced: Use it for ordinary previews, practice tracks, and quick content edits.
- Fast: Use it to test whether the requested source is present before spending time on a higher-quality pass.
- Precision Mode: Try it when sources overlap heavily or the first result leaves obvious leakage.
SleekPost's social media AI tips are also useful for the publishing stage, especially when an extracted audio clip will become part of short-form content. Separation and content packaging are separate jobs, so keep the audio decision focused on intelligibility and artifact control.
Don't judge the result only through headphones. Check the isolated file, the remainder, and the original at matching levels. If the remainder still contains too much of the target, or the isolated output loses key syllables, revise the prompt or use a more demanding quality setting.
A short demonstration can make the workflow easier to follow:
Isolate Audio is one option for this prompt-based approach. It separates a described sound into its own file and supplies the remainder, which makes it practical for vocal extraction, dialogue cleanup, and targeted sound recovery when fixed four-stem categories don't match the recording.
Common Mistakes When Mixing Isolated Vocals
The extraction finishes, the vocal sounds clear enough, and the creator drops it over a new beat. Then the result feels pasted on. That usually isn't a single software failure. The vocal came from a finished mix, so it carries the original room, dynamics, tonal balance, and timing relationships. Removing the accompaniment doesn't remove that history.
The first mistake is treating the stem as a final master. An isolated vocal often needs level matching, corrective EQ, de-essing, and controlled ambience before it belongs in a new arrangement. Start with conservative processing. If you boost the high end to restore lost consonants, you may also amplify metallic residue and cymbal leakage.
Rebuild the environment carefully
A dry vocal placed over a wide backing track exposes the missing room. The opposite problem occurs when the extraction retains reverb from the original mix and you add a second, unrelated space. Use a short room or plate to establish continuity, then keep the send low enough that the original ambience doesn't become obvious.
Phase deserves attention when the vocal is combined with the original song or a partially reconstructed track. Keep the separated vocal and replacement backing in compatible timing, audition in mono, and watch for hollowing when you blend related versions of the same mix. A polarity flip isn't a universal fix. It can remove some shared content while damaging the vocal you wanted to keep.
Make the artifact fit the arrangement
- Use automation before heavy compression. Level unstable phrases manually so the compressor doesn't exaggerate leakage.
- Leave transient detail intact. Over-denoising can make consonants and breaths less intelligible than the original artifact.
- Mask selectively. A new pad, guitar, or percussion layer can hide residue, but don't bury the vocal to conceal a failed extraction.
- Print a safety version. Keep the untouched separation beside every processed edit so you can return to the source.
If the vocal will be exposed in a sparse arrangement, inspect every important phrase. If it will sit inside a busy chorus, judge whether the artifacts remain audible after the complete mix is playing. The correct treatment depends on the delivery context, not on how impressive the solo sounds.
Choosing the Right Extraction Strategy
Start with the source, then define the consequence of failure. If authorized studio stems exist and the work is headed toward a commercial release, use them. They provide the predictable material required for detailed mixing, revision, and rights-aware production.
Use a conventional AI separator when you need a vocal or accompaniment from a finished song and can accept some leakage. It's a practical route for rehearsal tracks, mashup sketches, reference edits, and exploratory analysis. Before committing, listen to exposed phrases and compare the separated output with the original.
Natural-language separation makes more sense when the target isn't one of the usual music stems. A prompt-based system can address a piano line, a crowd, a particular voice, or another described sound, which is useful for video editors, podcasters, researchers, and field-recording workflows. Precision settings may help with overlap, but they won't remove the need for validation.
A compact decision framework:
- Need release-grade fidelity: Source official stems or return to the session.
- Need a fast vocal or acapella sketch: Test AI separation and mask or repair manageable artifacts.
- Need a specific non-musical sound: Describe the target in natural language and inspect both outputs.
- Need evidence or research data: Preserve the original, document processing, and test whether separation changes the feature being measured.
- Need spoken-word clarity: Compare intelligibility after processing, not just the apparent reduction in background noise.
The strongest workflow treats extraction as one stage in a chain. Identify the target, run a controlled separation, audition difficult passages, clean only what the task requires, and retain the original for comparison. That approach gets more value from modern AI without confusing an estimate with an authentic multitrack recording.
Isolate Audio lets you describe the sound you want, upload audio or video, and receive the isolated element alongside the remainder for tasks such as vocal extraction, dialogue cleanup, and targeted sound recovery. Try the workflow on a difficult mix or noisy recording by visiting Isolate Audio, then compare the result against the original before using it in production or analysis.